Training and rollout lifecycle
For a single adapter, miles exports the updated LoRA tensors at each configured publish boundary. Colocated jobs load them through the local tensor/IPC path; disaggregated Bridge jobs broadcast them to remote SGLang engines over NCCL. Rollout requests then select the live named adapter withlora_path.
Multi-LoRA currently supports disaggregated rollout only and rejects
--colocate at launch. Each SGLang engine keeps the base checkpoint resident;
adapter weights reach the engines through explicit pushes: each push registers
an immutable version under its own engine-side name, so in-flight sampling
against an older version is never disturbed.
Model support is therefore a three-way contract rather than a hard-coded
allowlist:
- Megatron-Bridge (or a model-specific provider) must build and wrap the training model.
- miles must map and export the selected module names correctly.
- SGLang must be able to allocate and apply the same adapter modules.
LoRA training implementations
Both implementations use--train-backend megatron. The difference is how
LoRA is attached to the Megatron model and converted for serving; this is
separate from SGLang’s serving-side --sglang-lora-backend choice.
The planned maintenance direction is native-first: after the generalized native plugin
lands, new model enablement and ongoing LoRA maintenance will primarily target
the native path. Bridge remains the compatibility path for existing validated
recipes during the transition; this is not an immediate Bridge deprecation.
Native LoRA
Native LoRA attaches adapter modules directly to raw-mode Megatron models instead of relying on Bridge PEFT conversion. The implementation onmain is
model-specific to Inkling and Inkling-Small. Generalized model-provider support
is under development in open PR #1792
and is not released on main.
Validated models and recipes
The table distinguishes CI-tested configurations from maintained recipes or full-scale experiment evidence. It is not an exhaustive model whitelist.Quick start
Append the following to a Megatron dense-model recipe:--lora-rank 0 is the default and disables LoRA when no adapter path is
provided. For RL, dropout is normally set to zero. Alpha is recipe-dependent:
maintained recipes use both alpha = rank and alpha = 2 * rank.
Omitting --target-modules or passing all-linear uses the model defaults from
miles/utils/lora/hf_lora_targets.py: attention + MLP, with model-specific exclusions
and output-head defaults. Multi-LoRA without explicit targets selects all three
training groups. Use --target-modules attn,mlp,unembed to select groups explicitly.
Ordinary LoRA also accepts specific HF targets mixed with group names, such as
--target-modules attn,lm_head; Tinker accepts only group names.
Core arguments
HF target source of truth
miles/utils/lora/hf_lora_targets.py owns HF target groups and defaults for all
backends. It derives attention, MLP, and output-head paths from the model config,
including nested text models, optional MLA projections, expert layouts, and
hybrid attention. Vision towers, routers, norms, and GDN convolutions are excluded.
--target-modules accepts comma-separated attn, mlp, and unembed groups,
explicit HF targets, or a mix of both. Group names expand through the model’s HF
definition, so mlp includes dense, shared, and routed expert projections, including
packed gate_up_proj weights. Only exact group names expand; full paths remain
literal target patterns. Duplicates are removed, then --exclude-modules applies.
Explicit module selections must not overlap exclusions; defaults and group
selections may still be narrowed with exclusions.
A matching pair of gate_proj and up_proj selectors also selects
gate_up_proj when the HF model has packed projections, with a warning.
Scoped pairs retain their path prefix; selecting only gate or only up does not
expand to the packed projection. Split selectors remain where the model has
split modules and are replaced where it has only packed modules.
Without explicit targets, ordinary LoRA uses its model defaults and multi-LoRA
selects all three groups. all-linear selects the ordinary model defaults and
must be used alone. Explicit lists replace the defaults.
Packed expert entries identify HF parameters rather than nn.Linear modules.
Inkling entries follow the native HF model namespace. Its native Megatron LoRA
implementation requires the complete fixed layout. SGLang discovers its adapter
modules with all, and online weight-sync config uses all-linear; adapter
checkpoints derive explicit names from exported tensors. Adapter factors, tensor
packing, and checkpoint names are unchanged. The pinned Transformers version does
not yet include native Inkling, so its HF structure is not covered by the native
meta-model tests. A layout entry is not a backend support claim.
Ordinary LoRA and Tinker share these HF target groups. HF targets retain their
meaning throughout training and serving. miles/utils/hf_utils/weight_mapping.py
uses Transformers conversion rules and a meta model’s parameter names to relate
checkpoint keys to the current HF model namespace, without loading base weights.
This resolves renamed and packed parameter names. Custom models absent from
native Transformers keep their existing checkpoint namespace.
Bridge resolves mappings against parameters that actually exist across PP/EP
ranks before checking fused selections. Explicit Megatron selectors retain a
compatibility conversion at startup. Adapter factories receive only Megatron
targets; they do not overwrite the HF selection. Arbitrary layer/expert subsets
within a registry template are not implemented and are rejected.
Standard LoRA requires all projections of a fused weight together;
canonical_lora supports individual Q/K/V and dense gate/up selections.
Grouped-expert FC1 and GDN input projections remain fused and require all of
their HF projections even in canonical mode.
Tinker uses --target-modules attn,mlp,unembed by default; for example,
--target-modules attn,mlp disables output-head training. Client SDK flags must
match the selected server groups. Tinker rejects explicit module names,
all-linear, and --exclude-modules because the SDK describes only whole groups.
For Bridge, SGLang receives the selected HF paths and normalizes them into buffer types
(for example, Q/K/V become qkv_proj); it does not own the selection policy.
Adapter checkpoints derive their concrete target_modules from exported tensor
keys rather than a separate Megatron-to-HF name table. Online adapter registration
uses the resolved HF selection for Bridge and all-linear for native Inkling,
without an extra tensor export.
This requires SGLang’s HF-path normalization support,
including GDN split names. FSDP LoRA injection remains
unsupported.
Native Inkling
uses a fixed model-specific adapter schema: defaults select that complete schema,
and partial/custom layouts or canonical_lora are rejected before injection.
Use the Inkling launcher defaults.
Rollout topology
The current native Inkling path is colocated only. Remote/disaggregated LoRA
sync on
main requires Bridge.
LoRA is not supported by the P2P/RDMA or disk-delta weight-transfer modes. A
hybrid job with both colocated and additional remote rollout engines also cannot
send LoRA weights to the remote engines today.
The legacy --lora-sync-from-tensor flag is still accepted by the parser but is
not consumed by the implementation. The topology selects the synchronization
path automatically; do not rely on this flag.
MoE adapters
This section describes the Bridge path; native Inkling uses its fixed custom expert layout. For grouped MoE experts, the training and serving layouts must agree. A typical Bridge configuration is:triton backend is required by the maintained MoE recipes; the
default backend can skip MoE layers. Per-expert adapters are the default.
--experts-shared-outer-loras selects the shared-outer layout, and miles enables
SGLang virtual-expert serving for expert adapters by default. Use
--no-sglang-lora-use-virtual-experts only when intentionally selecting the
alternative aligned-expert path.
Supported features
- Losses and algorithms. LoRA wraps the actor model independently of the policy loss. The maintained RL recipes use critic-free estimators such as GRPO. The SFT loss path can use the same adapter hooks, although the repository does not yet have a dedicated LoRA-SFT E2E test. Shared actor/critic PPO with Bridge LoRA is untested: the critic is always built as a full model without adapters.
- Checkpoints. miles saves native per-rank adapter shards and
optimizer/scheduler state. Exact resume expects the same TP/PP topology. It
also attempts a best-effort HF PEFT
adapter_model.safetensorsplusadapter_config.jsonexport in Bridge mode, through the same snapshot publisher used by Tinker. HF export errors are logged while native checkpoint saving continues. Raw mode saves native shards and a rank-sharded adapter config without HF export.--save-hfexports a merged model and an HF adapter without native training shards. Direct HF PEFT-to-Bridge resume is not implemented yet; native Inkling supplies a model-specific HF adapter importer. - Weight synchronization. Colocated IPC and remote NCCL broadcast both ship adapter tensors at each configured update boundary without merging them into the base. A checksum checker is available for the colocated path.
- Model structures. Dense attention/MLP, MLA, GDN, multimodal models, models containing DSA, and both per-expert and shared-outer MoE adapters have validated recipes or tests. DSA-indexer adapters themselves are not validated; see the model-specific caveats in the table above.
- Agentic sessions. Session-server requests carry the active single-LoRA name, so multi-turn trajectories are generated by the updated policy rather than the frozen base. See the experimental example below.
Quantized rollout
Precision support is asymmetric: the validated FP8 configuration trains the LoRA actor in BF16 while SGLang serves a separately quantized FP8 base checkpoint. Adapter tensors remain unquantized and are synchronized at each configured weight-update boundary. The GLM-5.2 launcher exposes this as its--fp8-rollout option and writes an SGLang config with update_weights: true.
See Low Precision RL and
INT4 QAT for the underlying precision features.
Historical GLM-5.2 validation measured:
These values are configuration-specific rather than universal FP8 thresholds.
The full-744B row is historical multi-node evidence and cannot be reproduced
directly by the current single-node
main launcher; multi-node launcher work is
tracked in PR #2033.
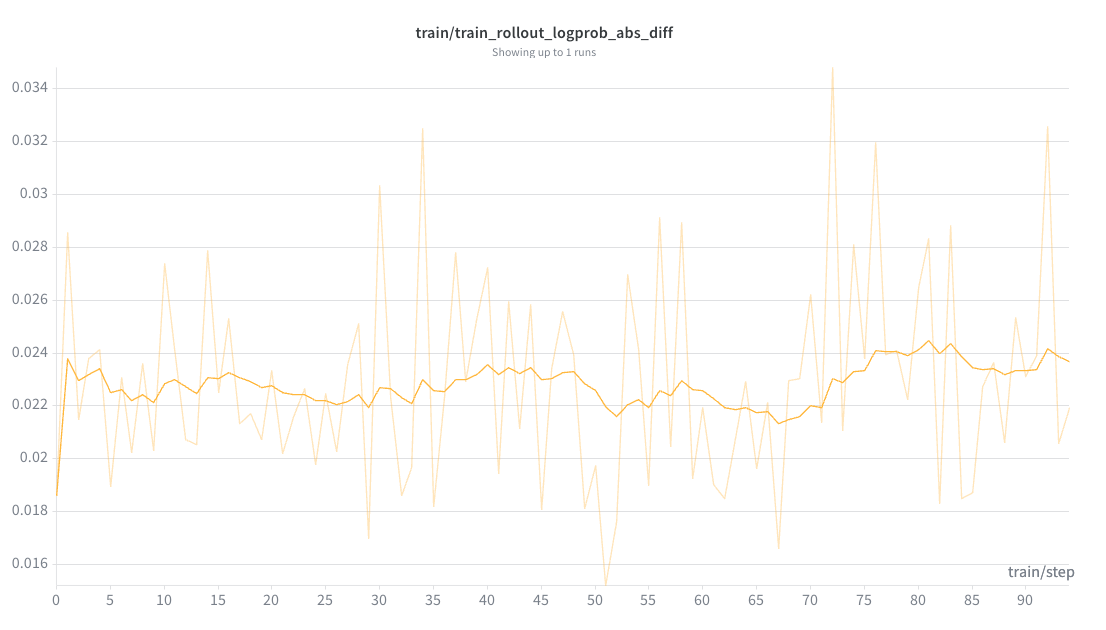
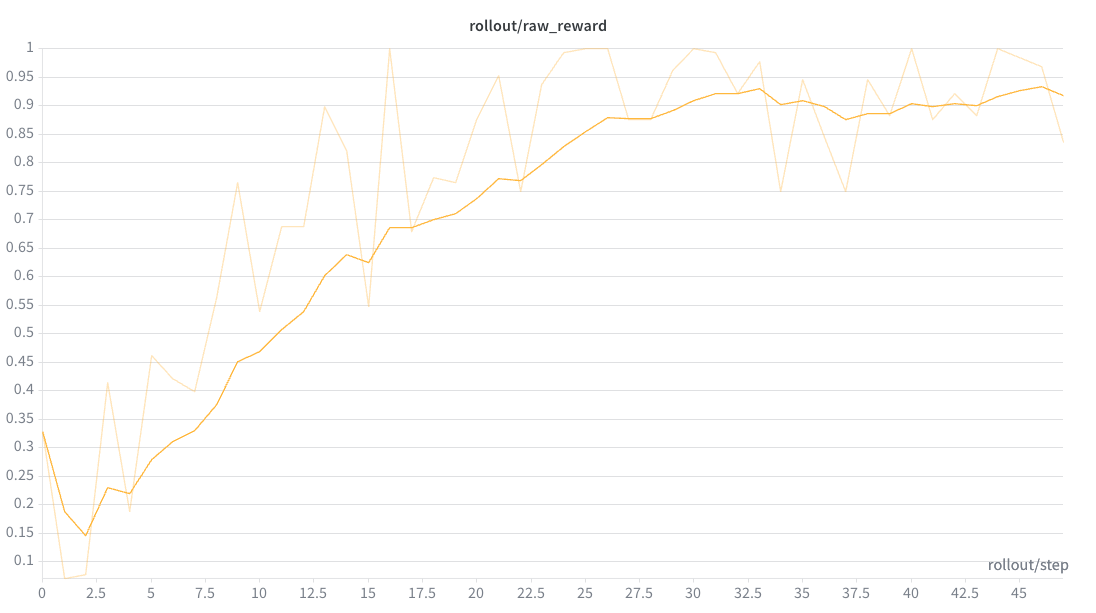
The same work also produced the following curves from a different, longer
validation run. The exact configuration for these curves was not published, so
their plotted levels should not be mapped to any one of the final point
measurements in the table:
GLM-5.2 744B BF16 validation
Historical full-scale runs validated the GLM-5/5.1/5.2 Bridge LoRA path across MoE and MLA on models containing DSA; the DSA indexer itself was excluded from the adapter targets. The full GLM-5.2 744B run used 64 GPUs and completed more than 50 rollout -> train -> save steps. The validation also compared expert target selections, including a run that excludeddown_proj.
Treat this as historical implementation and scale evidence. The reported
train/rollout log-prob gaps are configuration-specific and are not established
as a portable acceptance threshold, so the corresponding curves are not
reproduced here.
Agentic RL with LoRA (experimental)
Agentic rollout has one extra correctness requirement: every turn sent through the session server must select the newly synchronized adapter. The session server therefore attacheslora_path=miles_lora to its requests; otherwise the
trainer could update LoRA while the agent continues collecting trajectories
from the frozen base policy. The current session integration selects the fixed
single-adapter name; it is not multi-LoRA slot routing, and it should not be
combined with --lora-train-only.
Draft PR #2280 adds the first
LoRA-specific agentic recipe: GLM-5.2 744B-A40B with synchronous GRPO on
Terminal-Bench-2-style tasks, a Harbor agent server, and Daytona sandboxes. Its
reference configuration uses:
- 4 nodes x 8 H200, TP8 / EP32 / PP1 / CP1;
- BF16 training with an FP8 rollout checkpoint;
- rank 16, alpha 32, attention/MLA-only targets;
- 64K sessions, TileLang DSA, full recompute, and disk actor offload; and
- two 16-GPU rollout engines with
--lora-base-cpu-backup.
Multi-LoRA training
Multi-LoRA training is served through the Tinker protocol:serve_tinker.py
turns a miles deployment into a training service where each client drives its
own adapter slot with explicit forward_backward / optim_step operations (the
server owns no datasets or schedules). The gateway lives in miles/tinker/,
the slot mechanics in miles/backends/megatron_utils/lora/. The dataset-driven
multi-LoRA v1 backend (fully-async driver, adapter controller, per-adapter data
sources) has been removed.
Clients use the official tinker SDK with the gateway URL and a distinct API key
per tenant. The key identifies ownership of models, futures, and checkpoints.
Each adapter accumulates gradients until its client submits an optimizer step;
saving weights for sampling publishes an immutable adapter version.
save_state saves adapter parameters and optimizer state, including FP32 masters.
It waits for preceding commands but neither steps nor saves pending gradients;
call it after optim_step to save the effect of the accumulated training work.
Sampler saves commit an immutable adapter directory on shared storage, without
contacting inference engines. Engines load the same frozen base at startup and
load adapter snapshots from disk on demand. A failed engine load fails sampling
without invalidating the saved snapshot or model training.
Futures, model leases, and sequence deduplication are in memory and are lost on
gateway restart. Saved checkpoints retain their ownership and adapter metadata
and can be used to create a new training or sampling client.
See the gateway example for the launcher and smoke client.