miles_plugins.models.inkling.model.inkling_mm_model_provider). Clips travel as shared file paths: SGLang’s
Inkling token-space strategy decodes each clip, turns it into dMel frames and expands the audio placeholder, and every
trainer rank rebuilds the same tensors from the files in the background (--multimodal-token-space-processing).
Data
prepare_avqa_audio.py writes every clip as 16 kHz mono WAV and two prompt files under avqa_audio/:
train.jsonl (29.6K AVQA questions) and avqa_heldout.jsonl (2K AVQA questions held out by clip, with a fixed seed
and the same share of every question type as the training data). The AVQA repack only carries the dataset’s training
subset, so the held-out slice is the eval set.
Run
avqa_audio task grades through examples/avqa_audio/reward.py: Inkling writes thinking blocks before the text
block that carries the letter, so the reward parses the response tokens with the Inkling response parser and hands
only the visible text to the GPQA letter grader. Grading the flat response instead reads letters out of the thinking
and scores a quarter of right answers as wrong.
Results
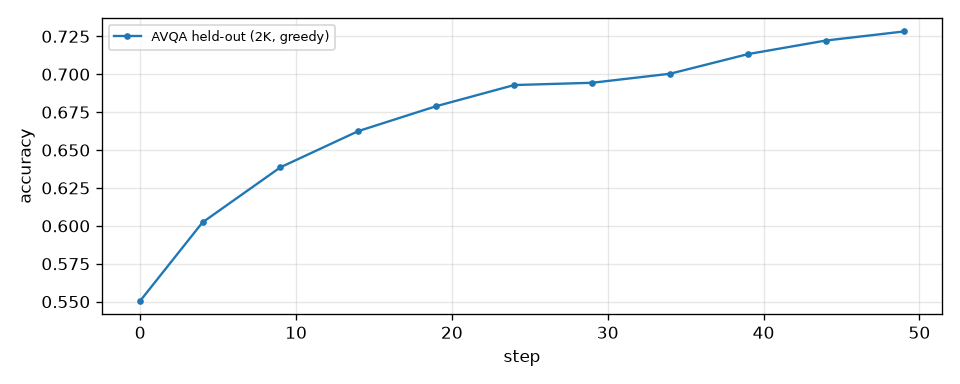
Inkling-Small LoRA, 50 steps on 8 H200, scored every 5 steps with greedy decoding:
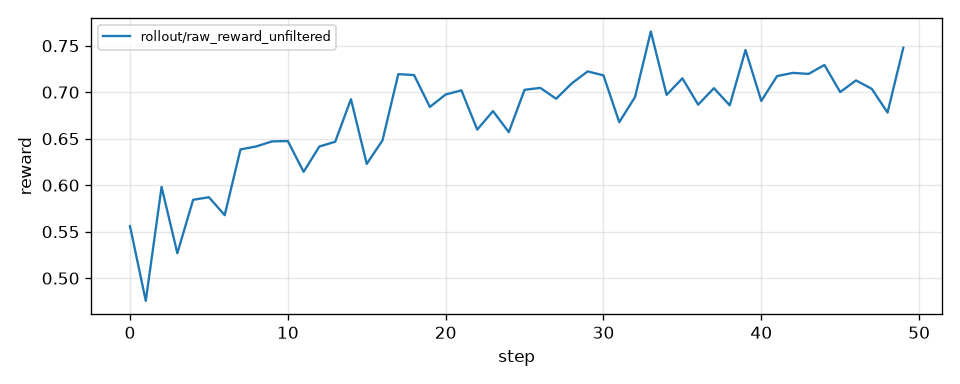
The held-out score rises 17.8 points and is still climbing at step 49. The training reward goes from 0.56 to
about 0.70.
Notes
- The AVQA repack only has the training subset (the official validation set ships YouTube links, not audio), so the held-out slice is cut from it: whole clips, a fixed seed, and the same share of every question type.
- Greedy evaluation of the same checkpoint moves by up to 0.6 points between runs, so single-point differences below that are noise.