Environment API (geo3k)
Environment API (geo3k)
build_env(sample: Sample | None = None, args: Any | None = None, **_) -> Geo3kEnv: constructs the env.reset() -> tuple[dict, dict]: clears internal state.step(response_text: str) -> tuple[dict, bool, dict]: parses the actor’s response text and update the state. Return new observation, a flag that marks whether the task is done, and step_info.format_observation(observation: dict) -> dict: converts an env observation into a chat message.
The reward model is the default math RM.
Reproduce
What each file does
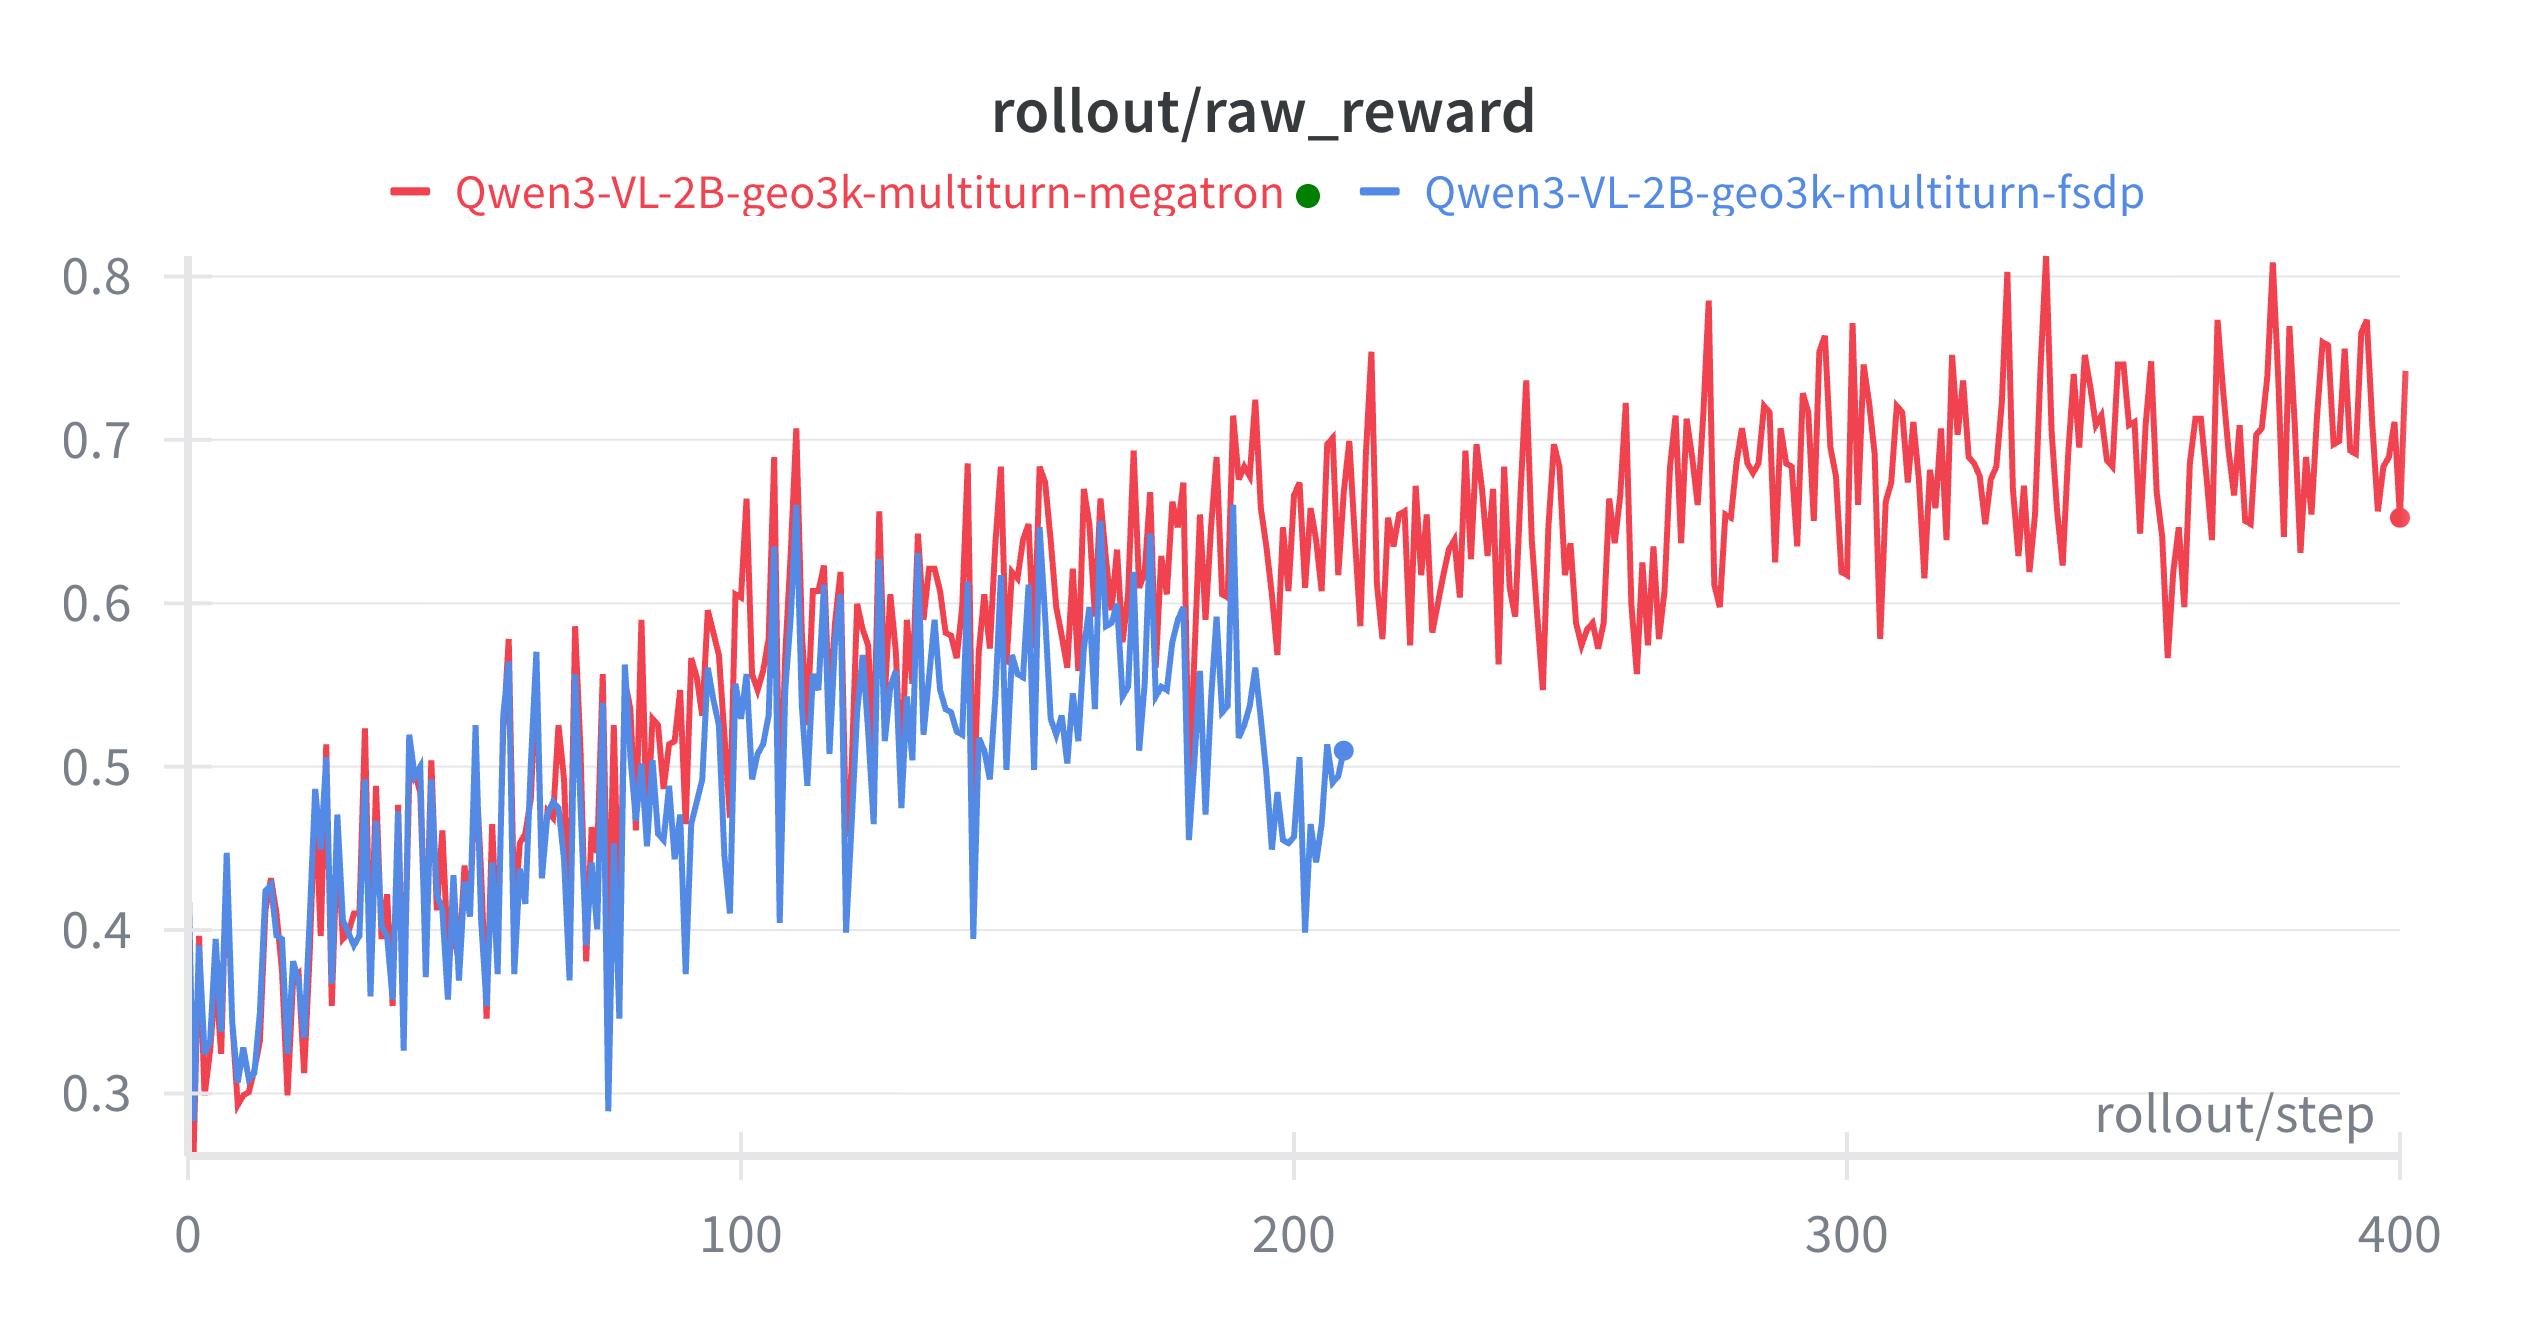
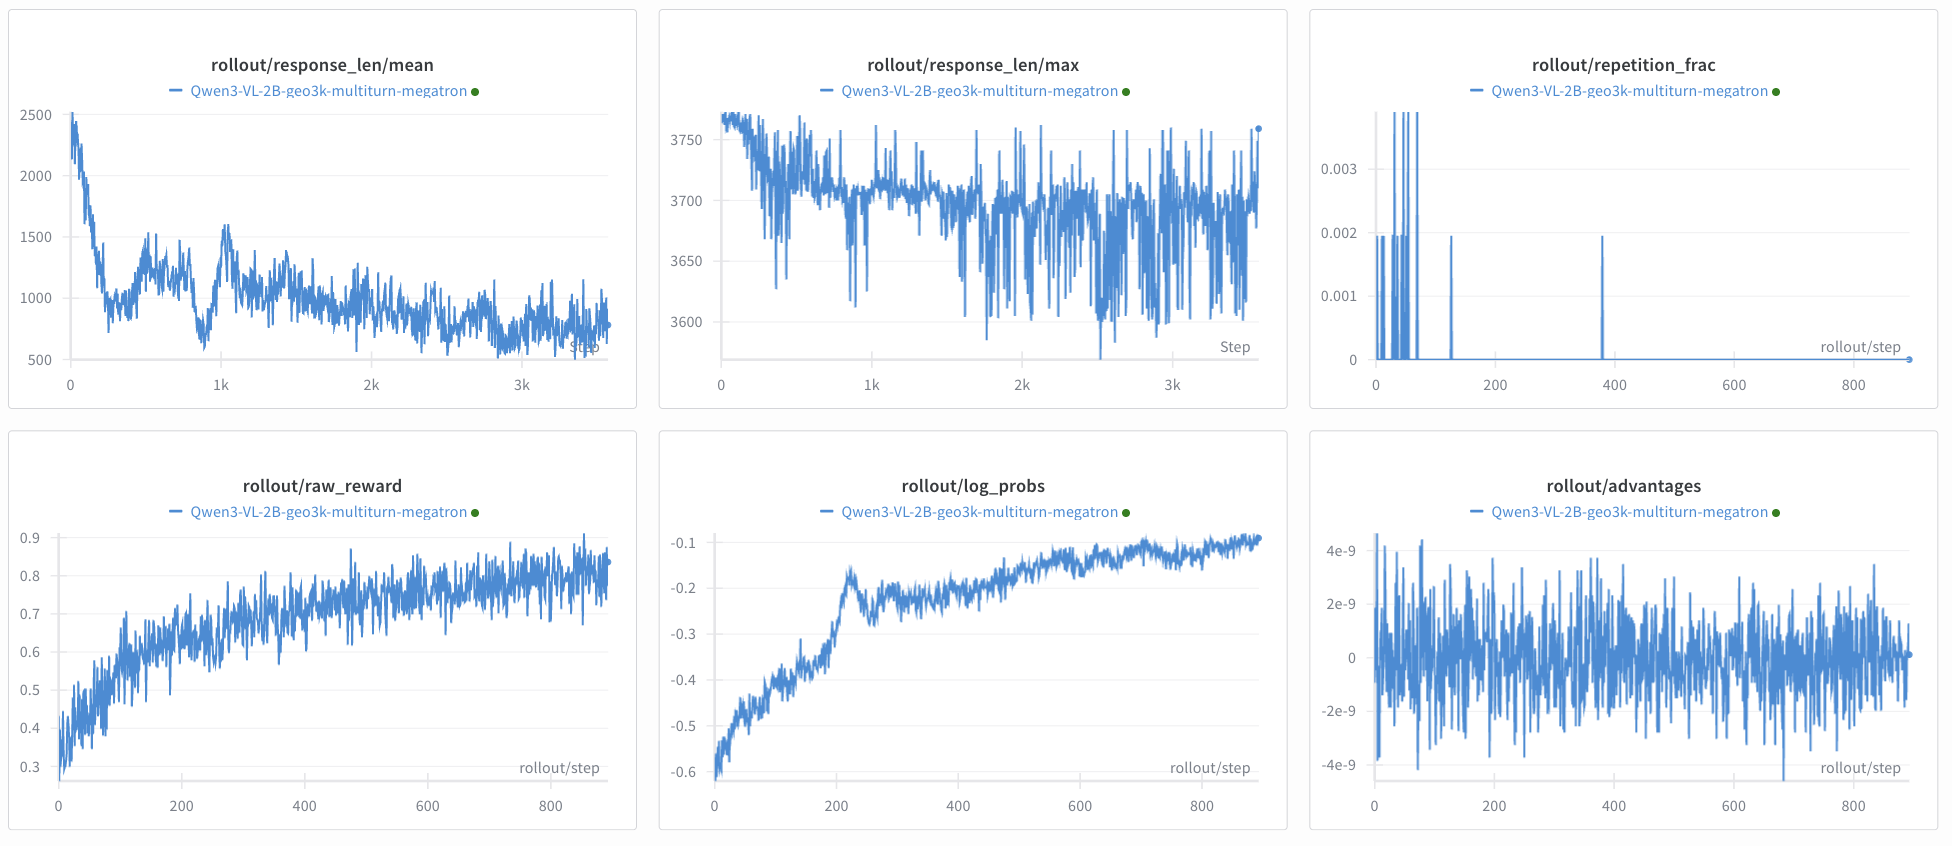
examples/geo3k_vlm/multi_turn/run_geo3k_vlm_multi_turn.py: downloads model, sets training/rollout args, and launches the run.examples/geo3k_vlm/multi_turn/geo3k_vlm_multi_turn_config.yaml: specifiesmax_turnsandrollout_interaction_env_pathfor the multi-turn rollout.examples/geo3k_vlm/multi_turn/rollout.py: custom multi-turn rollout that calls SGLang for token generation, builds loss masks/log_probs, enforces max_turns, and early-stops on max_new_tokens.examples/geo3k_vlm/multi_turn/env_geo3k.py: geo3k tool-calling env that parses <tool_call>{…}</tool_call>, scores math answers, and returns tool feedback per turn.