Data Preparation (For SFT Training)
The geo3k_imgurl dataset contains:problem: The math problem text (string)answer: The answer (string, e.g., “270”)images: Image data (list)
answer field for \boxed{} format and the messages. You can use the following script to format the answer field:
Reproduce
Configuration
Supported Models
Qwen3-VL-2B-InstructQwen3-VL-4B-InstructQwen3-VL-8B-InstructQwen3-VL-30B-A3B-InstructQwen3-VL-235B-A22B-InstructQwen3-VL-2B-ThinkingQwen3-VL-4B-ThinkingQwen3-VL-8B-ThinkingQwen3-VL-30B-A3B-ThinkingQwen3-VL-235B-A22B-Thinking
Training with Token Space Processing
Models whose SGLang build has a token-space strategy can run on the token-space processor instead of the Miles-side HF processor: SGLang expands one placeholder token per image and computes the vision features, and every trainer rank rebuilds the same tensors from the files under--shared-media-dir (--multimodal-token-space-processing with
--sglang-enable-token-space-processor; Megatron backend only; on multi-node runs that directory must be a shared filesystem).
One processor on both sides (zero train/rollout diff), one shared custom preprocessing cache, token-in/token-out (TITO) engines.
Notes
Reward Model Configuration
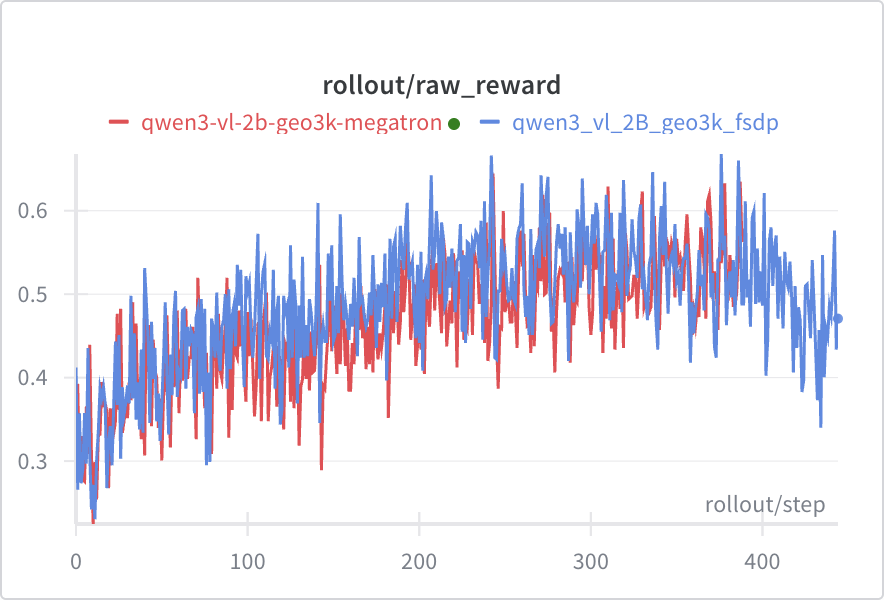
We experimented with three reward model configurations:- A geo3k-specific RM with tolerance=0.05 (to handle rounding in ground truth labels)
- A geo3k-specific RM with tolerance=0.0 (strict matching)
- The default math RM
Numerical Precision with Non-Binary Rewards
Our initial geo3k-specific verifier produced “format scores” (0 and 0.9) instead of clean binary rewards. Under fp32, fractional values like 0.9 can’t be exactly represented, so when all samples in a group have the same reward,reward - mean doesn’t equal zero—creating spurious gradient signal.
We fixed this by switching to the default math RM with clean binary 0/1 rewards. If you encounter similar precision issues with non-binary rewards, you can change the reward tensor dtype from torch.float to torch.float16 in miles/ray/rollout/train_data_conversion.py (_post_process_rewards) to truncate precision artifacts.
B200
Blackwell currently does not support fa3, we need to use--sglang-mm-attention-backend sdpa and --attn-implementation flash_attention_2