miles_plugins.models.qwen3_5.qwen3_5_mm_model_provider). Videos travel as shared file paths: SGLang samples the
frames and expands the placeholders in token space, and every trainer rank rebuilds the same tensors from the files
in the background (--multimodal-token-space-processing).
Data
prepare_data.py writes timelens_grpo_train.parquet (2.5K prompts, sampled by difficulty as TimeLens does) and
timelens_bench_charades_600.parquet (600 Charades items for eval). The parquets store absolute video paths.
Run
torch_dist (the multimodal model keeps the text model’s
parameter names), and trains 300 steps of 16 prompts x 8 samples on 8 GPUs, evaluating Charades every 10 steps.
The trainer and the engines share the GPUs and offload in turn. The vision tower is frozen, and every weight sync
re-sends it from the checkpoint, so the engines get it back after each offload.
--model-name Qwen3.5-35B-A3B runs the MoE on the same node: the trainer trains TP2 x EP4 with the Adam state on
the host and replays the engines’ expert routing, the engines take 2 GPUs each, run the vision tower unsharded like
the trainer (--sglang-mm-enable-dp-encoder) and cache the per-video features on disk, and each step samples
32 prompts x 8.
Results
Qwen3.5-9B, 300 steps on 8 H200 (TP4), scored every 10 steps on 600 held-out Charades-STA items (none of the training videos come from Charades): tIoU 0.48 at step 0, 0.56-0.57 from step 150 on, best 0.573.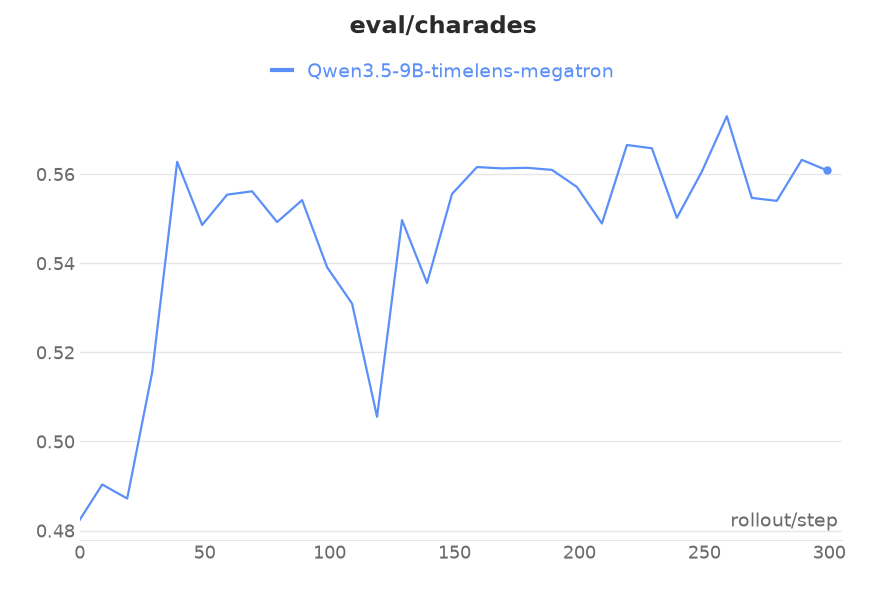
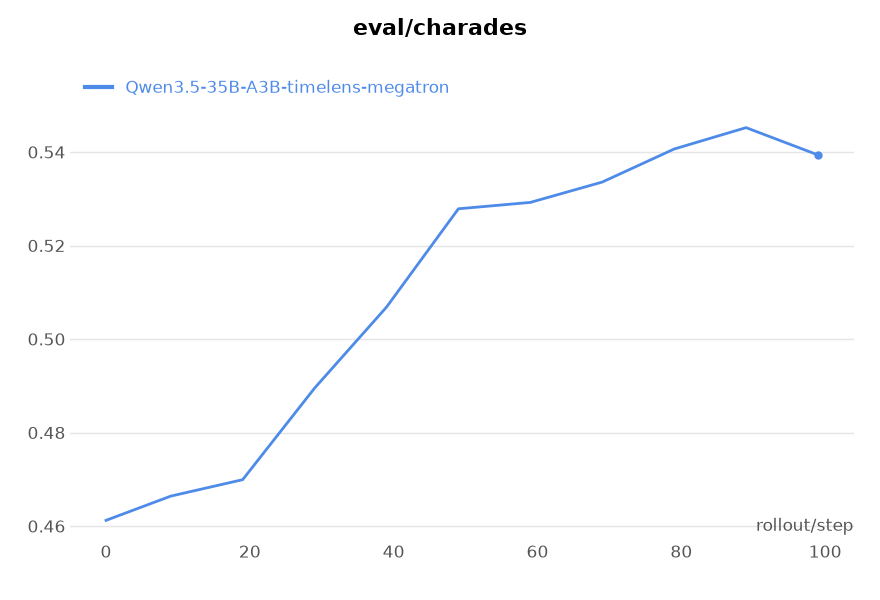
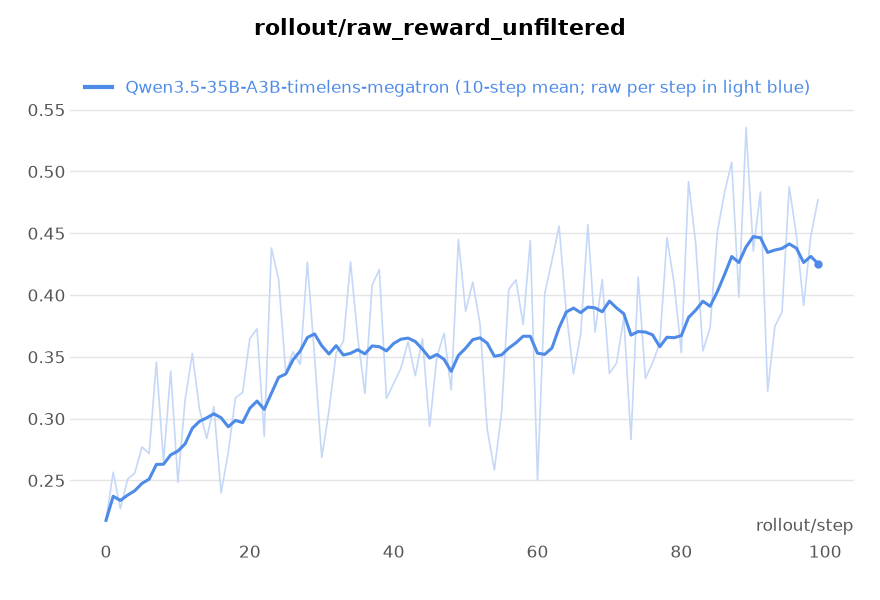
 Qwen3.5-35B-A3B, 100 steps on 8 H200 (TP2 x EP4), scored every 10 steps on the same 600 items: tIoU 0.46 at step 0,
0.53-0.55 from step 50 on, best 0.545.
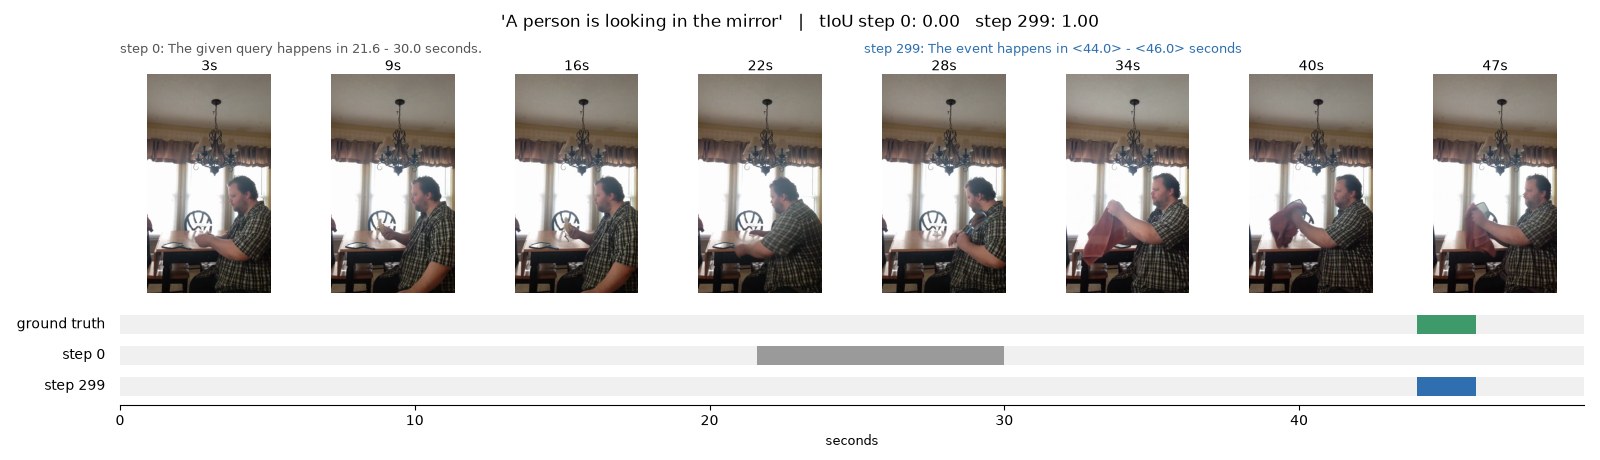
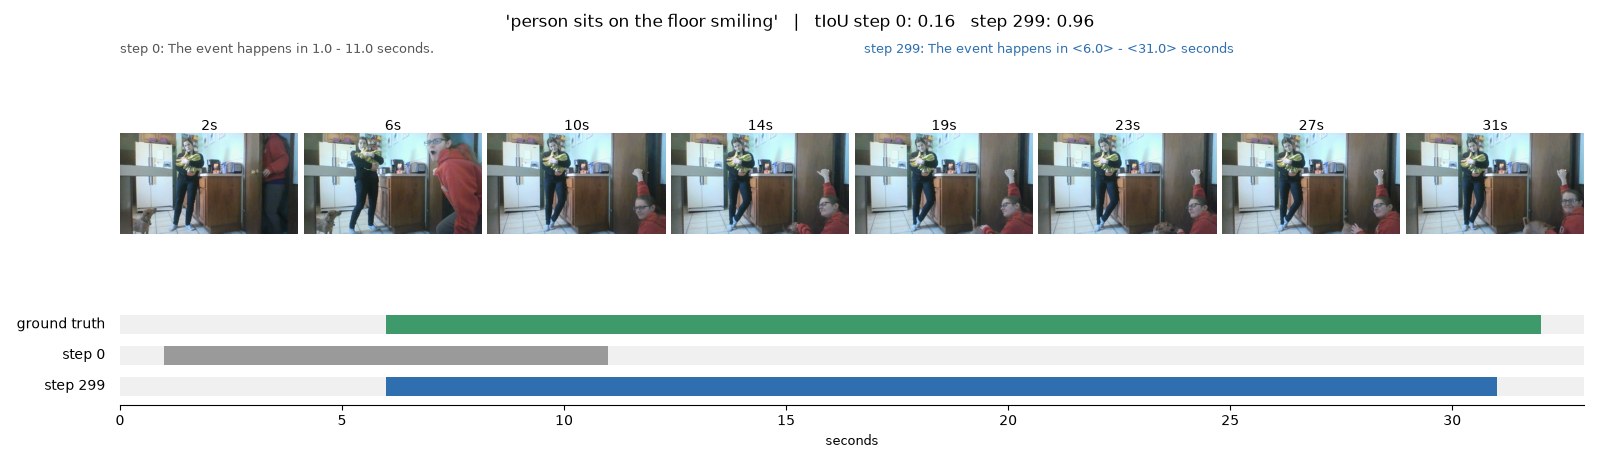
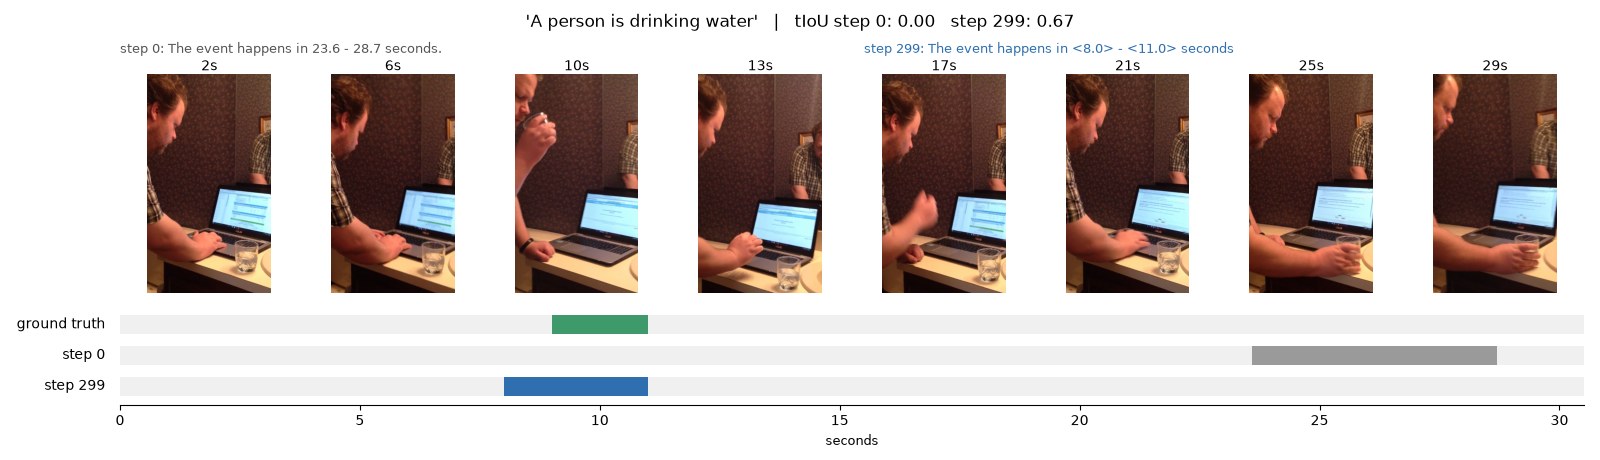
 Three held-out Charades items, answered by the model at step 0 and at step 299. Each strip shows eight frames of the
video and, below them, the ground-truth span (green), the step-0 prediction (gray) and the step-299 prediction (blue).
Over the 600 items, 180 improve by more than 0.2 tIoU and 68 get worse by more than 0.2.
Notes
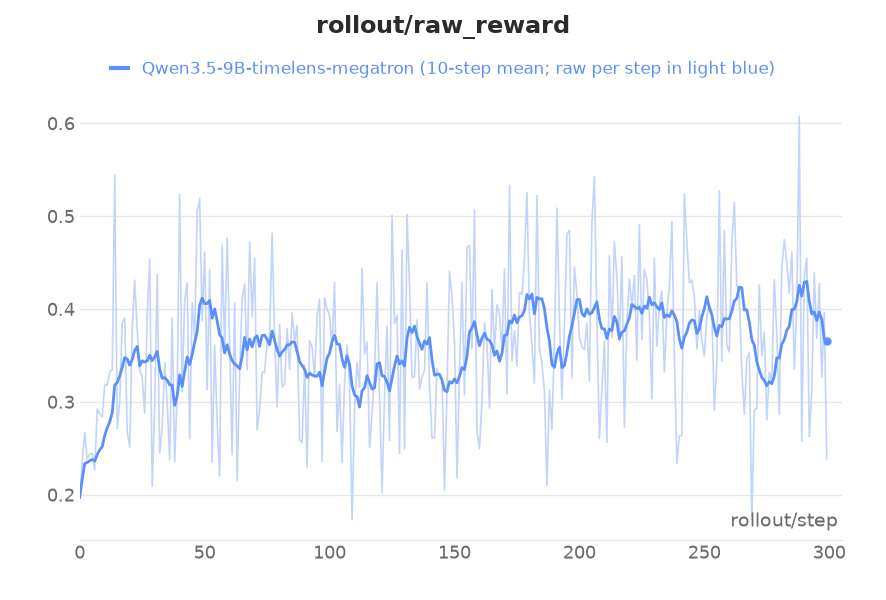
- Responses cut at the 512-token limit score 0 in training (
zero_truncated_rewards): the tIoU reward reads only the first predicted span, so text after it is free, and without this step a run grew its answers to the 512-token limit for the second half of training. Eval keeps the TimeLens scoring. - 300 steps x 16 prompts is about two passes over the 2.5K prompts.